Document Workflows
Logistics Document Processing for Automated Freight Operations
Document processing determines how much freight automation actually works.
Priya Subramaniam10 min read
Geometry, not model quality, determines whether PDF table extraction actually works in production.
Document processing determines how much freight automation actually works.
Extraction errors at the document layer cause cascading PA denials downstream.
Vision models solve layout and context problems that break traditional document processing.
Extraction errors at intake undermine every downstream AP automation step.
How hidden choices in building ground truth datasets mask the real causes of extraction failures.
Four structural causes drive extraction failures on fields that business workflows depend on.
Vendors mix four different metrics into one accuracy claim, causing pipelines to fail in production.
Understanding three layers reveals why confidence scores don't mean what they appear to.
Real-world documents reveal why benchmark accuracy scores collapse once models enter production.
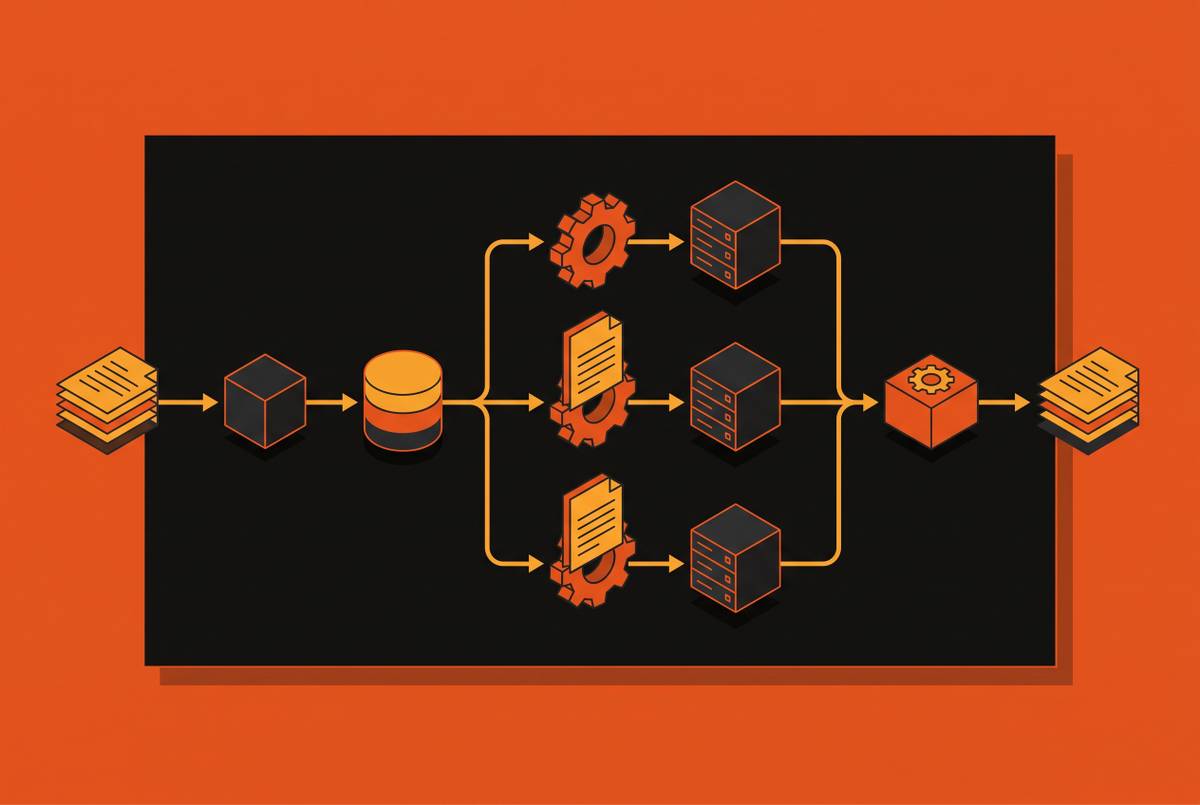
Document pipelines need idempotency engineered separately at each processing stage.
Document extraction needs different reliability patterns than payment webhooks.