Agent Pipeline
Structured Output Schema Design for Document Extraction APIs
Schema design matters more than model choice for extraction accuracy past a few dozen fields.
Priya Subramaniam11 min read
External state management, not bigger models, fixes multi-page document reasoning in production.
Schema design matters more than model choice for extraction accuracy past a few dozen fields.
Routing low-confidence extractions prevents review queues from becoming bottlenecks.
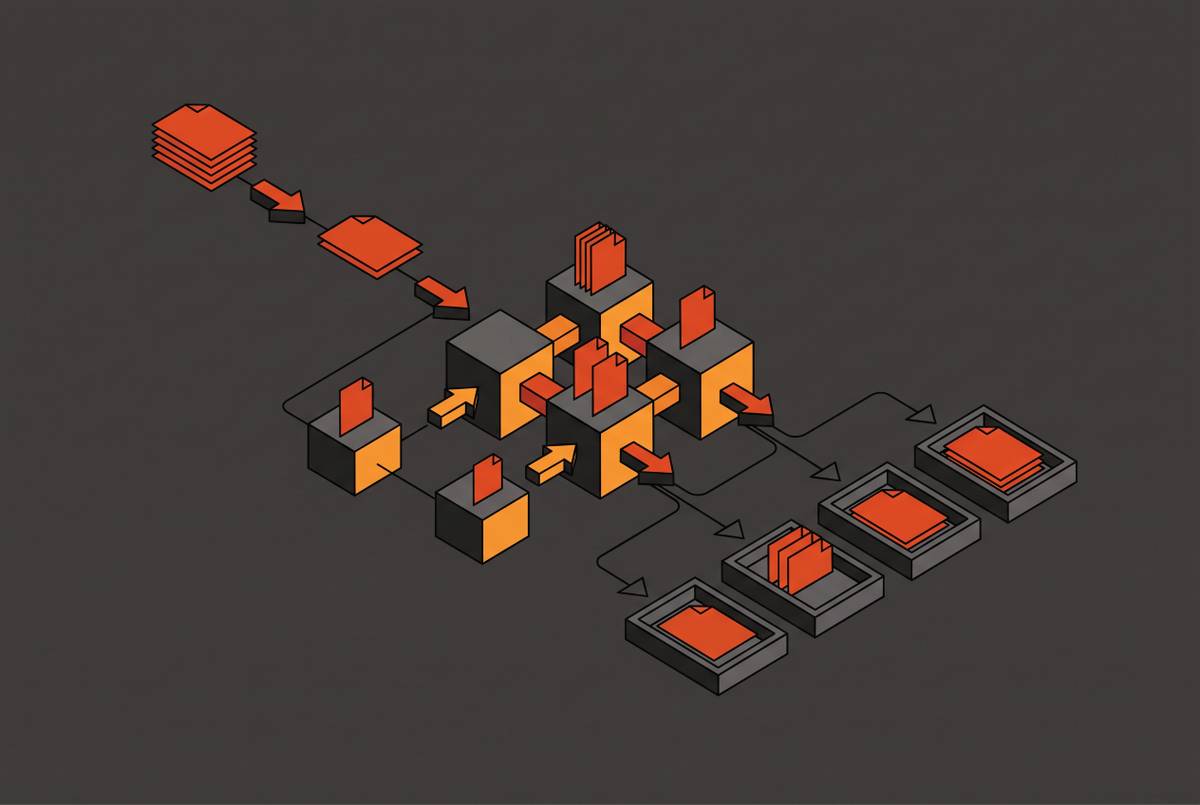
System design, not model quality, determines whether document pipelines hold up in production.
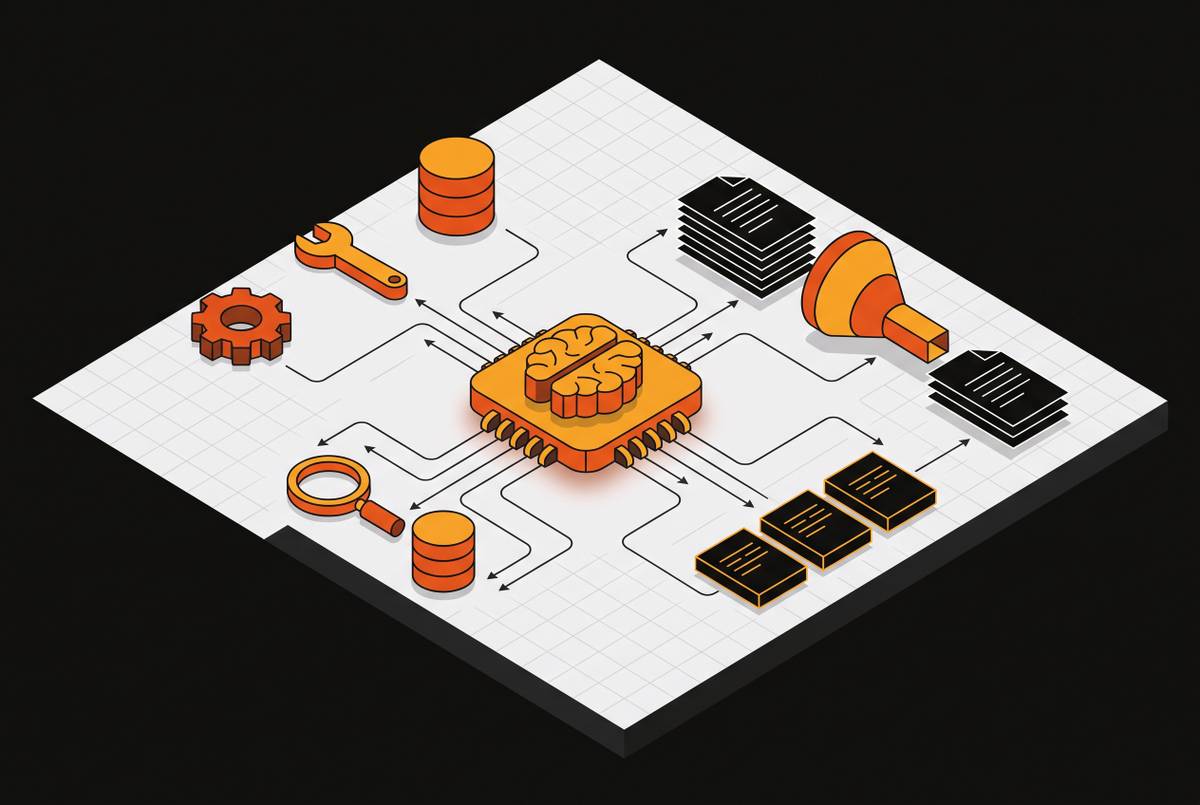
Structured tool-calling architecture beats monolithic LLM prompts for production document workflows.
Misclassified documents and missed fallbacks sink pipelines faster than bad parsing.
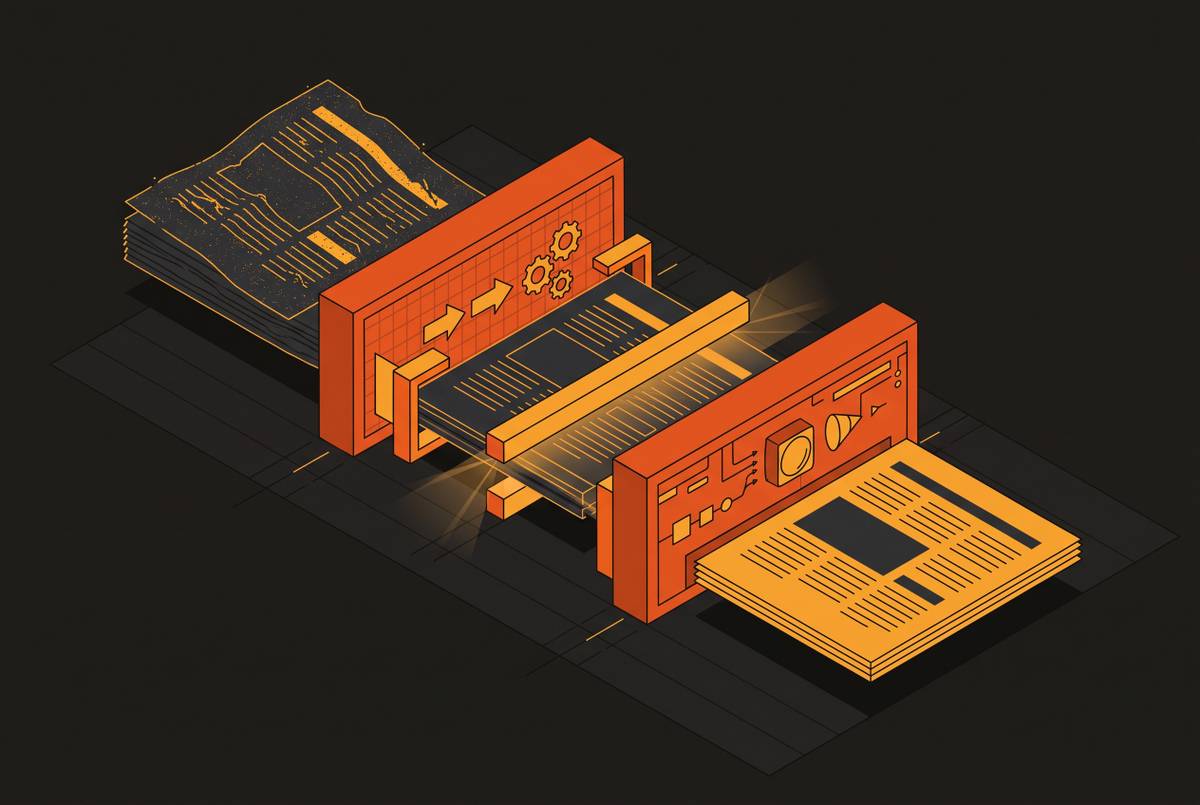
Fixing blurry, skewed, or damaged scans beats upgrading the OCR engine itself.
Silent encoding errors compound across document pipelines undetected.
Understanding field relationships requires parsing layout before text extraction.
Choose a parser by what your pipeline can't survive getting wrong, not by benchmark headlines.
Handwritten text recognition fails silently in ways printed OCR never anticipated.
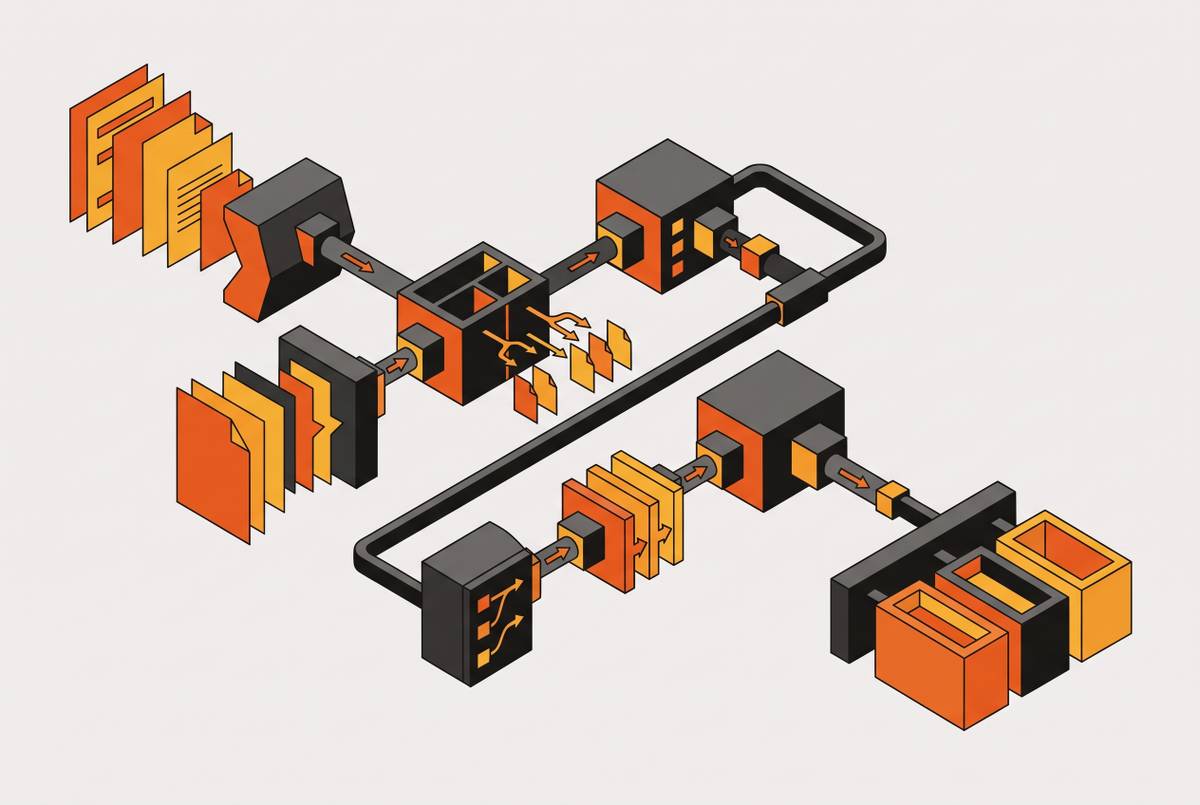
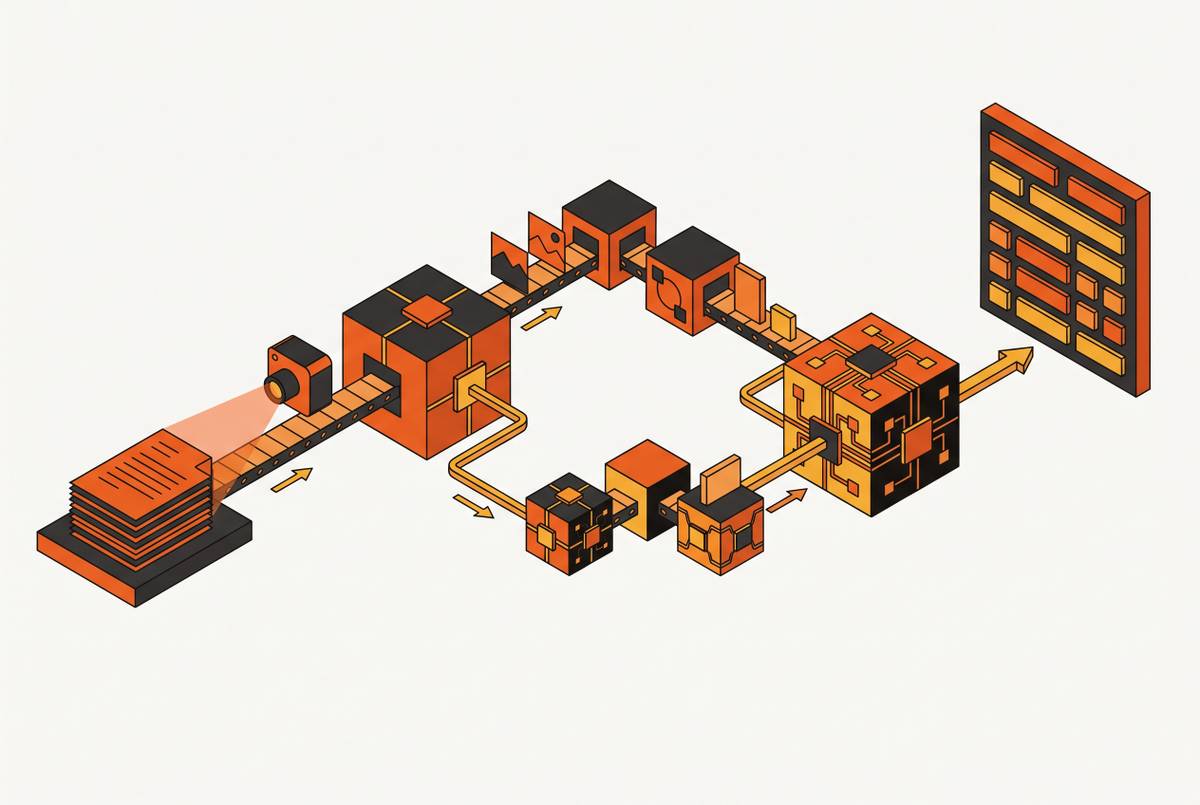
Order matters: layout analysis, then OCR, then reasoning for accurate document parsing.