Evaluating Document Parsing Layers for Production AI Pipeline Reliability
Test your parser on the documents your pipeline actually processes, not public leaderboards.
Production AI agents need document processing infrastructure that preserves layout, reading order, and table structure, returns traceable values with calibrated confidence scores, and routes uncertain results for review. The best parsing layer is the one that proves these properties on the documents the pipeline actually processes. Clean-test OCR accuracy alone cannot show that a parser will work reliably in production.
Why standard OCR benchmarks fail to predict production parser reliability
A team selects the highest-ranked model on a leaderboard, then sees it fail on the first production batch. Leaderboards rank performance on static test sets, while production introduces changing layouts, degraded scans, and relationships that cross page boundaries.
Character Error Rate (CER) treats incorrectly recognized characters uniformly, although a wrong digit in an invoice total has different consequences from a typo in boilerplate. F1 balances precision and recall but can reward broad field recovery while obscuring failures on rare, high-consequence documents. Neither establishes whether correctly recognized text belongs to the right field or appears in the right reading sequence.
The test documents also constrain what scores reveal. Stable layouts do not expose layout variability, and born-digital PDFs do not test the recognition problems introduced by scans. The test’s coverage has gaps in assessing whether a parser resolves references or preserves table structure across pages when scoring is performed per page.
The four jobs a production parser must get right simultaneously
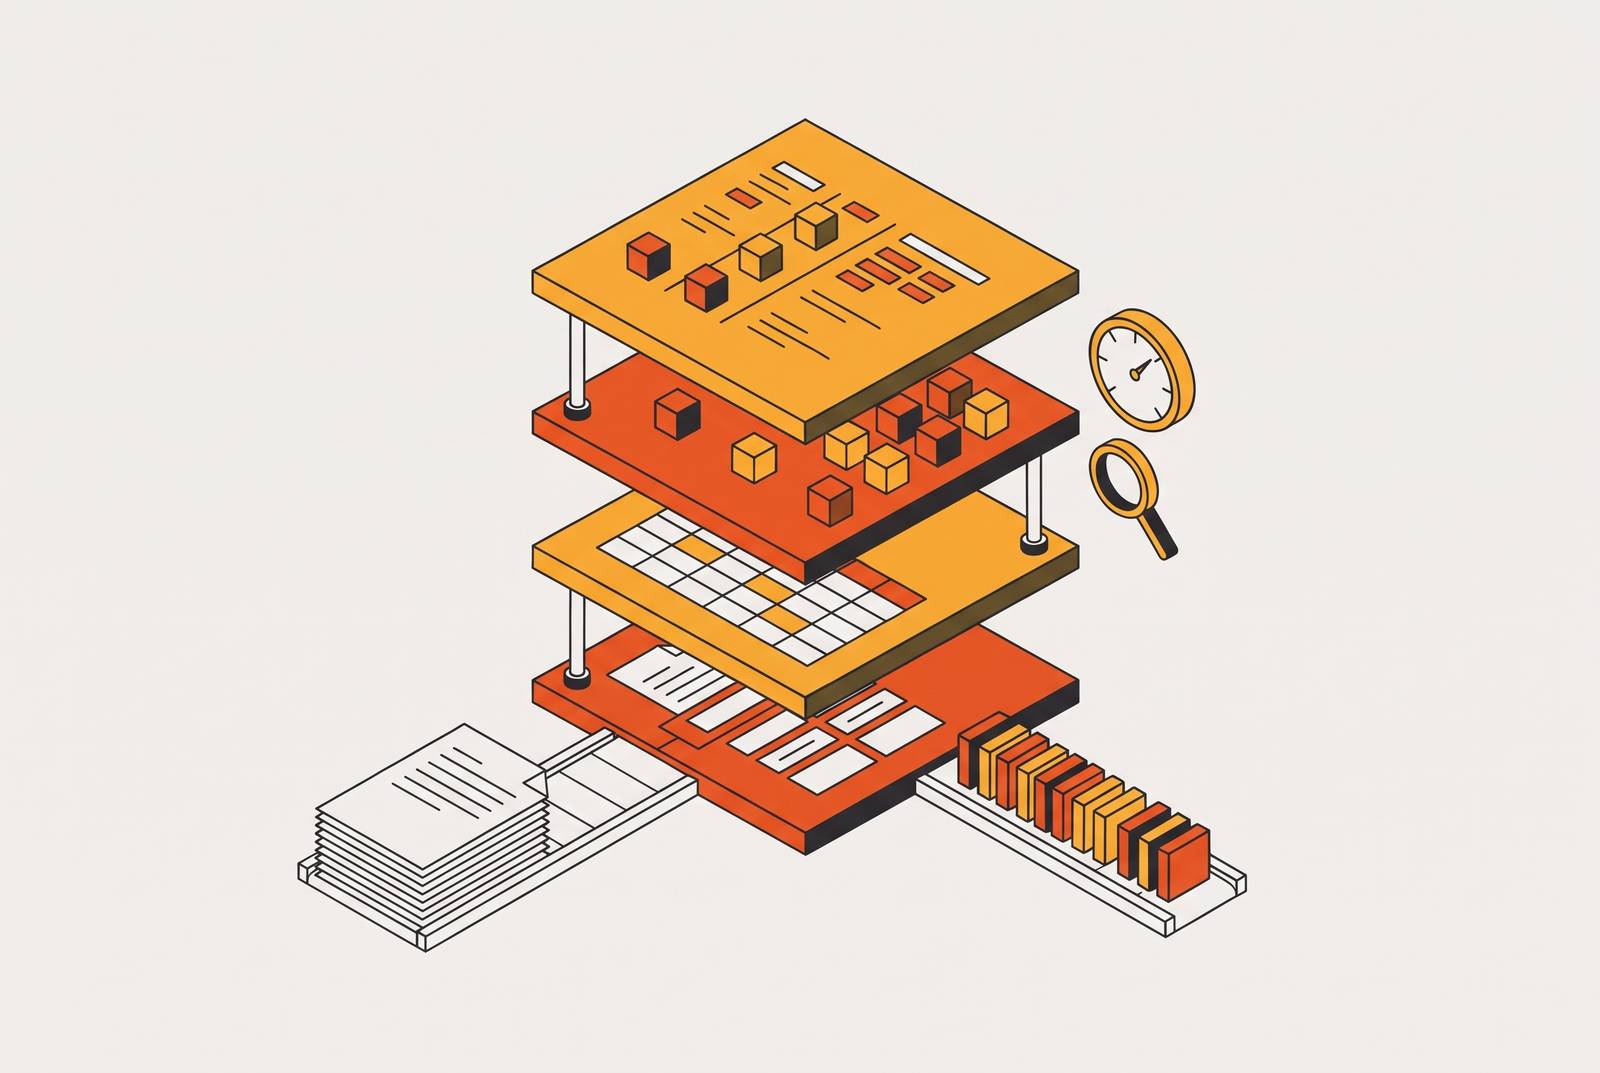
Production parsing combines four jobs, namely layout detection, OCR, table reconstruction, and reading-order preservation. Layout detection identifies regions such as tables, headers, forms, figures, and key-value pairs before text is read. Misclassifying a region can leave its characters intact but place them in the wrong semantic context. OCR must then recognize the text itself. A misread digit remains an error even when the surrounding layout is reconstructed correctly.
Table reconstruction recovers the relationships between rows, columns, and headers. A table that continues onto another page must retain the header-to-column mapping even when the header appears only on the first page. Reading-order preservation solves a different problem, keeping content in the sequence a downstream model should read and keeping separate columns from being interleaved. Correct words are not enough on their own. Character accuracy and structural accuracy can move independently, so a composite score cannot identify which of these jobs failed.
Why open-source parsers break at the specific points production documents stress
Open-source tools can serve clean, text-layer PDFs with predictable layouts well. Their limits follow from their design scope. PyMuPDF (fitz) performs well on digitally native PDFs and supports OCR through Tesseract or RapidOCR, but low-resolution scans, irregular fonts, and handwriting challenge accuracy without dedicated preprocessing. pdfplumber works well on structured PDFs but has no built-in OCR, while irregular spacing and merged cells can disrupt cell alignment.
Camelot automatically detects table boundaries and optionally accepts explicit region coordinates through table_areas and table_regions. That flexibility does not remove the risk of silent extraction failures when layouts vary. Apache Tika supports many formats for mixed-format ingestion and comes with the overhead of JVM infrastructure, but it does not specialize in table-extraction. These tools address different parts of the problem. Their suitability depends on the document conditions and structural requirements of the pipeline.
Production tables expose the distinction between extracting visible content and reconstructing its meaning. Nested tables complicate structure, embedded sub-headers can become data rows, and right-aligned numeric columns can shift when font output varies across PDF generators. Across pages, lost header mappings leave rows without field attribution. Configuration can address particular cases, but it does not by itself supply layout inference or cross-page context resolution.
The evaluation dimensions that separate production-grade parsers from demo-grade ones
Reading order should be scored separately from text accuracy across multi-column pages, sidebars, captions, footnotes, and nested lists. Table tests should cover merged cells, spanning headers, borderless tables, and rows that split across pages. Header mappings must survive those page breaks. Otherwise, correct cell text can still produce incorrect downstream aggregation.
Tests must also check for failures that happen without warning. A dropped row, misread checkbox, or value assigned to the wrong label becomes harder to contain when the parser supplies no uncertainty signal. Minimum and average OCR confidence on chunks and blocks can help applications identify regions for review. Output completeness is equally important. Markdown may support retrieval, while viewers, audit tools, and extraction systems need typed blocks, page ranges, bounding boxes, source text, and confidence metadata within a stable, versioned contract.
Tests should go beyond layout-adjusted F1 to check whether document Q&A answers are correct, how well RAG retrieval works, and whether fields and arrays are complete. Deployment requirements belong in the same decision, including asynchronous jobs, rate limits, observability, zero data retention availability, and VPC or self-hosted options. Regulated workflows also require applicable SOC 2, HIPAA, and GDPR controls. These dimensions must be evaluated together, because strong layout recovery and convenient deployment cannot compensate for undetected data loss.
How to benchmark parsers against your own documents rather than public leaderboards
To apply this framework, teams should first assemble a corpus that represents the documents their pipeline will receive. It should cover born-digital PDFs, scans at varying resolutions, multi-column layouts, handwritten annotations, and files mixing digital and scanned pages. The corpus must cover the document types, languages, and page counts the pipeline will handle. Domain differences can make general averages misleading. Intentional edge cases should include page-spanning tables, irregular form spacing, rotated headers, and watermarks.
Next, check the fields and structure in the outputs against verified ground truth. Field accuracy establishes whether the value needed by the business workflow is correct, while field-level precision and recall reveal missing or incorrect values. CER measures OCR errors, Word Error Rate (WER) measures text errors, and Tree Edit Distance Similarity (TEDS) measures table structure. These metrics diagnose different failure classes. Parsing and extraction results must remain separate because reconstructing the full document and returning selected schema-bound fields are distinct tasks.
The evaluation should then test downstream task correctness using the same representative documents. RealDoc-Bench covers layout accuracy across logistics, healthcare, financial services, and real estate documents, together with document Q&A accuracy on parsed output. Its two tracks illustrate why both reconstruction and task performance need measurement. Public benchmarks remain a useful first filter. They cannot replace the workload-specific test.
For comparisons over time, teams should pin the benchmark version and retain the evaluation conditions. Scores from different versions of a benchmark suite are not directly comparable. Vendors that cite accuracy figures should share the dataset, document types, and conditions behind them. That information lets teams tell whether the results apply to their documents or come from cleaner inputs or a narrower range of them. It also prevents a change in the test from being mistaken for a change in parser quality.
Confidence scoring and silent failure modes as the production reliability gate
Operating the selected parser requires a routing architecture. Without calibrated confidence, reviewers have no reliable signal for triage and must review the entire output to establish trust. Review cost then becomes the operational constraint alongside the API fee. Calibration is the prerequisite for selective review. A confidence score that does not correlate with actual accuracy creates false routing signals.
A clear policy lets high-confidence outputs go through automatically and sends medium-confidence cases to a reviewer with fields already pre-filled. Low-confidence cases should escalate as structured exception records. This policy depends on confidence thresholds and fallback behavior built into the pipeline. Grounding must also be verifiable at the field level. Bounding boxes and source text tied to extracted values give reviewers and applications evidence against which to check the output.
Completeness needs explicit treatment within that architecture. Dropping rows from a table with thousands of entries may have little effect on an aggregate field score while leaving the workflow with an incomplete dataset. Evaluation must penalize dropped rows. Confidence metadata does not excuse missing data. Grounding checks, completeness tests, and routing policy must work together to contain failures before they become accepted workflow inputs.
How parsing accuracy in the ingestion layer determines downstream AI agent quality
An agent’s reasoning begins with the representation ingestion provides. If parsing drops a table header, extraction can assign values to the wrong fields, and the agent then receives incorrect inputs that appear usable. The resulting workflow error inherits the original structural mistake. Later stages cannot reliably diagnose that origin from the corrupted representation alone. Improving reasoning without addressing ingestion leaves this causal chain intact.
The output contract determines what the agent can verify. Typed blocks keep each part’s content role, page ranges and bounding boxes show where the evidence is, and source text links extracted values back to the document. Confidence metadata gives the workflow a basis for deciding whether an output can proceed. A wall of text lacks that attribution. Even when its words are correct, the agent cannot use it to substantiate a claim at a source location.
Ingestion and extraction features determine what the system can process, but surfacing and handling failures requires confidence scoring and integration depth. A demo that works may test only the first pair. Production reliability requires the second pair because the agent’s output is only as dependable as the evidence and controls available to it.
What document processing infrastructure do AI agents need in production?
A complete parsing layer is a coordinated system of parsing, extraction, classification, splitting, and workflow orchestration APIs. Parsing reconstructs the document, while a separate extraction endpoint returns schema-bound JSON with per-field confidence and source citations. Processing modes let teams tune accuracy, cost, and latency for each use case. Classification picks the right processing configuration for the document type. Splitting breaks up compound files and multi-document packets so the right pages go to the right workflow.
PyMuPDF and pdfplumber can serve suitable clean-PDF workloads, table-extraction tools address tables, and Tika supports mixed-format ingestion. Google Document AI offers managed OCR, form, layout, custom extraction, classification, and splitting processors for teams native to its cloud platform. Each option still needs workload-specific evaluation. No component’s category fit establishes the reliability of the complete workflow.
At volume, batch queues support asynchronous work, while webhooks and observable job states expose processing failures. Built-in evaluation should include schema versioning, evaluation sets, and automated accuracy reports at field and document level. Continuous benchmarking against representative files makes regressions detectable before deployment. Debugging support belongs in the same system. Typed SDKs for Python, TypeScript, Java, and Go, a CLI, MCP support, and installable agent skill templates help developers and coding agents build workflows, while a review UI exposes bounding boxes and confidence metadata for inspection.
Compliance must also be an infrastructure property. Zero data retention policies and self-hosted or VPC deployment options give regulated workflows controls, but those workflows need more than a choice of where to run. PCI-scope processing requires network segmentation, encryption, access control, and logging, whether cloud-hosted or self-hosted, while HIPAA workflows require a HIPAA BAA. These capabilities must be available as infrastructure options. A production selection therefore rests on demonstrated document fidelity, traceable uncertainty, and operational controls together.
Sources
- OCR Benchmarks & Real-World Documents (July 2026)
- Doc Parsing: Open Source vs. Production APIs August 2026
- 9 Best Document Parsing APIs in 2026
- Best Document AI Evaluation Tools (February 2026)
- 7 Document Extraction APIs Ranked by Accuracy
- 11 Best Document Processing APIs for Developers (2026)
- 6 PDF Parsing APIs for AI Agents