Document Ingestion Contracts Every Agentic Workflow Needs Before It Reaches Production
Six pipeline contracts enforce the guarantees that keep document ingestion reliable.
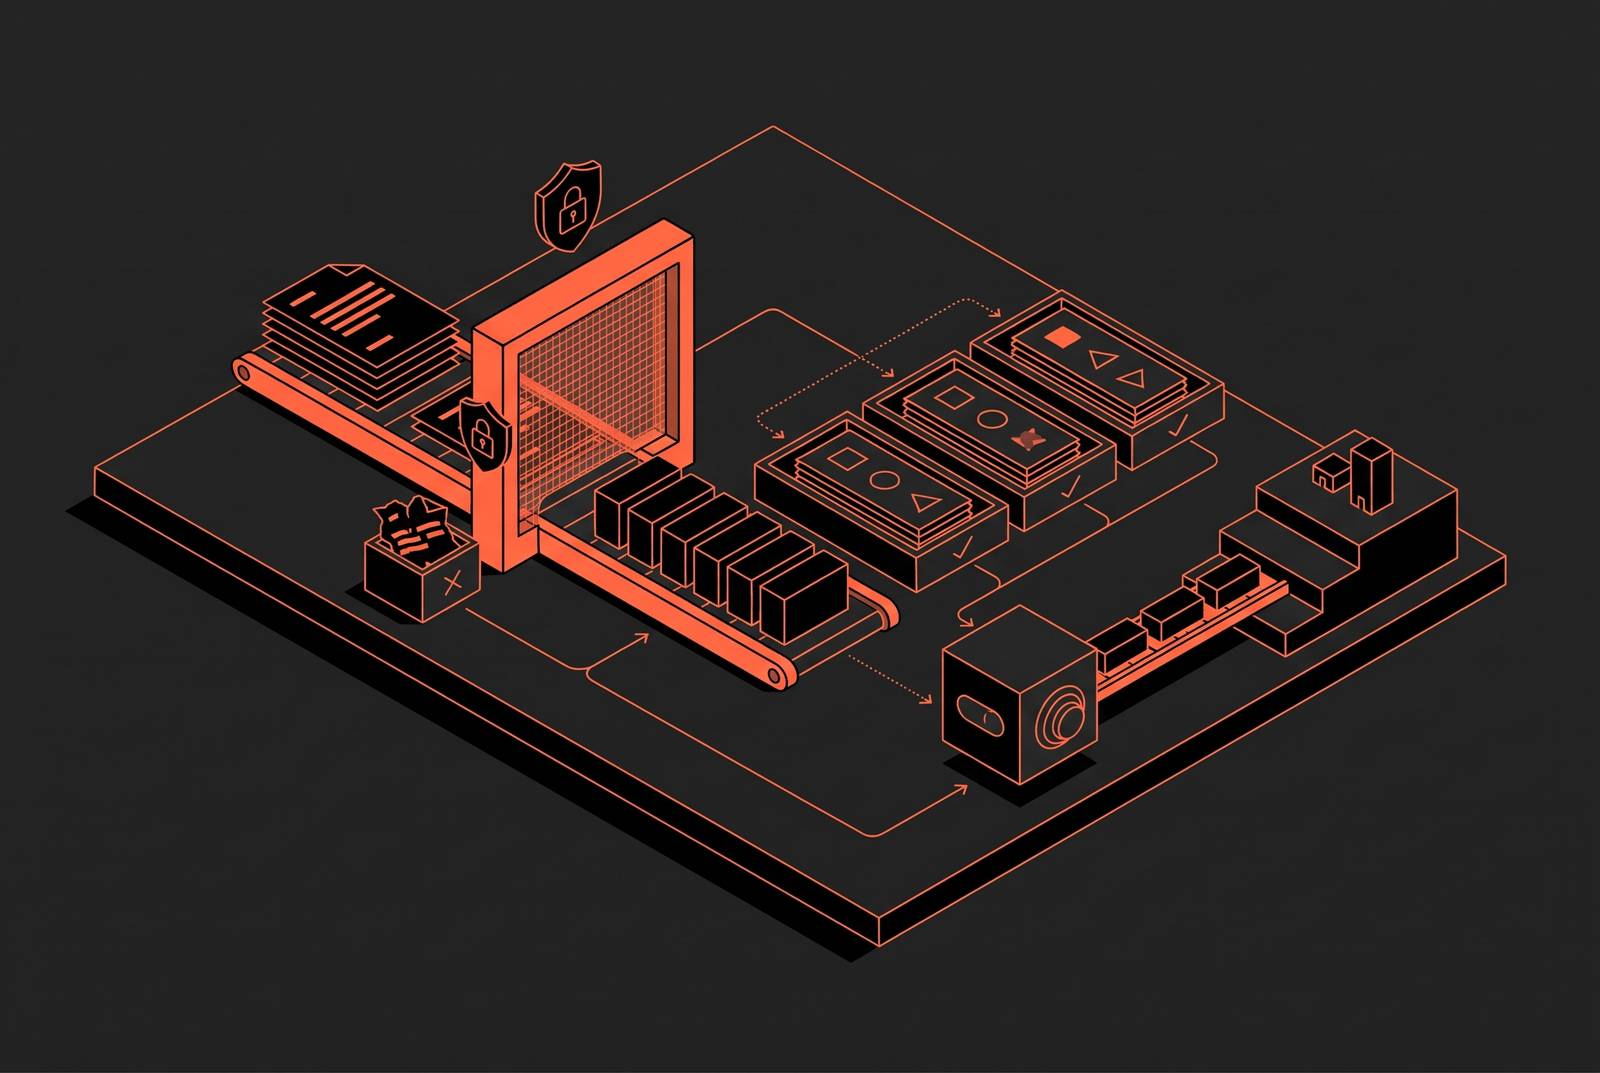
Production document processing infrastructure for AI agents needs six enforceable contracts covering parsing, chunking, embedding and indexing, validation, handoff, and auditability. These contracts define what each boundary must preserve, what it must reject, and what evidence must accompany the result. Reliability depends on enforcing them together, because an ingestion failure compounds through every downstream stage.
Why the ingestion layer is where agentic workflows actually break
Multi-page contracts and scanned intake forms can break extraction pipelines before an agent gets any data. Parsing loses cross-page context, while validation gaps allow low-confidence fields into downstream systems. The resulting failure appears to belong to the agent. But the failure starts in the representation the agent got, which may look sound even though it lacks information the agent needs to make the decision.
That makes production reliability a pipeline problem. The five stages are parsing, chunking, embedding and indexing, validation, and agent handoff. Each stage depends on guarantees made by the preceding one. When those guarantees are implicit, a defect can travel through the whole chain before it becomes visible as an incorrect action.
What a "contract" means in this context and why the word is the right one
A contract is a behavioral guarantee that one pipeline stage makes to the next about the form, completeness, and trustworthiness of its output. It defines an interface whose obligations can be tested and whose violations can be detected. The distinction from a processing step is enforceability. A step describes work performed, while a contract specifies the conditions under which its result is acceptable. Across the five stages, that framing makes validation and rejection part of normal operation.
The parse contract: layout-faithful, structured output before any downstream step
Changes in layout break extractors that rely on columns being arranged in a familiar way. A new format can cause them to assign values to the wrong fields without producing an obvious error. Page-by-page processing introduces a different loss of meaning. A value on page 4 may depend on a definition on page 1, but an isolated page representation severs that relationship. Mixed PDFs, Word files, and images add inconsistent text layers, encoding differences, and display artifacts that defeat uniform extraction logic.
The required output is a structured, LLM-ready representation that preserves spatial relationships, table structure, header hierarchy, and cross-page references. Every document type the pipeline gets must meet that requirement before downstream processing starts, no matter how complex the layout, how good the scan, or what the format is. A parser that drops a table row breaks the contract even if the rest of the text it returns is readable.
Agentic parsing addresses these demands by treating document processing as a reasoning task. VLMs analyze visual layout, then route regions to specialized models, including handwriting recognition for handwritten sections and table extraction for dense tables. Their outputs merge into coherent structured data. The acceptance criterion remains the resulting representation. A parser that silently misreads a column header still corrupts the fields derived from that header.
The chunking contract: segment boundaries that preserve semantic units and cross-page context
Even when a document representation is true to the source, splitting it into retrieval units can make it unreliable. The chunking contract requires boundaries at semantically coherent breaks, without losing the cross-page or cross-section context needed to interpret a passage. A fixed size alone cannot give that guarantee. A boundary that cuts a clause in half can leave both fragments readable but neither sufficient for an agent to act correctly.
Hierarchical chunking preserves parent-child relationships between sections and passages, making it appropriate for multi-page contracts and loan packages. When a passage is insufficient, the agent can move up the hierarchy to obtain surrounding context. Semantic chunking instead follows meaning boundaries in heterogeneous documents whose sections vary widely in length. Fixed-size chunking remains fast and predictable for uniform corpora with consistent content density and no need for hierarchical relationships. The strategy follows the document’s structure.
Metadata is part of the chunking contract itself. Each chunk must make enough sense on its own for retrieval and keep enough parent context to recover its wider scope when needed. That includes its section heading, page number, and document-level identifier. A passage cut off from those fields loses provenance even if its words stay the same.
The embedding and indexing contract: retrieval that surfaces the right chunk for the right query
The embedding and indexing contract requires retrieval to surface the chunk containing the answer, rather than a topically adjacent passage that shares its vocabulary. This depends on preserving the whole retrieval unit during encoding. A chunk larger than the embedding model’s context window can be silently truncated, leaving a vector that represents only a fragment. The chunk may have passed its own contract. Its guarantee nevertheless breaks at the encoding boundary.
An index built without section-level metadata cannot filter by section, forcing retrieval across an undifferentiated corpus when narrower context was available upstream. Context capacity and index structure are therefore contractual properties. Per-stage latency and error rates help show failures that metrics for the whole pipeline hide, including whether embedding or index construction is the bottleneck.
The validation contract: three checkpoints that catch errors before they reach the agent
Validation is a three-checkpoint system. The post-parse checkpoint checks that the structured representation contains expected regions, including tables, headers, and form fields, with none silently dropped. This check precedes reliance on extracted values because missing source structure can make later fields look complete when they are not. Any failed check must trigger review.
The post-extract checkpoint checks that required fields are present and that they meet the schema types, accepted value ranges, and confidence constraints. A numeric field populated with a string fails here, as does a date field populated with a currency value. Confidence also tests how sure the model is. Each extracted field gets a numeric score, and fields below the set threshold go to human review. Approval engines and compliance workflows require higher thresholds than internal reconciliation pipelines because their tolerance for error differs.
Those thresholds are only useful when confidence is calibrated against actual accuracy. A score is not proof of correctness. A threshold set on a validation corpus may work differently on production document distributions, letting unreliable fields through while holding back accurate ones. Calibration must therefore address both missed errors and unnecessary review. Over-routing is also a contract failure because it removes the automation benefit.
The pre-handoff checkpoint evaluates the payload as a whole. It must be schema-valid and confidence-complete before crossing into the agent layer, with nothing that failed an earlier checkpoint allowed through. This final check establishes that the earlier gates’ guarantees remain intact at the boundary where the agent will rely on them.
The handoff contract: a typed, schema-complete payload the agent consumes without additional cleaning
The handoff contract requires a payload the agent can consume directly, without cleaning, normalization, or field mapping. Every required field must be present and typed according to the agent’s schema. Every extracted value must keep its source page, document region, and confidence score. Preserved structure is insufficient if the final interface strips away the evidence needed to interpret or cite a value.
The payload format must also stay the same across document types, so the agent has no need for conditional handling when upstream formats differ. Enforcement belongs at the boundary. Otherwise, malformed inputs can cause failures that are hard to trace back to their source. The schema is an interface and requires versioning. An unversioned breaking change disrupts downstream agents in the same way a breaking API change disrupts clients.
Legal contract intake makes the operational stakes concrete. Agents receive inbound contracts, classify their type, extract key commercial terms, and route them with a coverage summary. Completing that work in minutes rather than days depends on receiving an actionable payload. If the agent must first interpret inconsistent fields or reconstruct missing context, the ingestion layer has not fulfilled its obligation.
The audit contract: an immutable trace from document ingestion through final agent action
The PCAOB’s amended AS 2201 has an effective date of December 15, 2026. That deadline makes it more urgent to be ready for an audit, but it does not set a technical specification that all agent pipelines must follow. The infrastructure requirement here is an immutable, citable trace from document arrival through final agent action. Accountability cannot depend on reconstructing events afterward.
The trace must record inputs, outputs, model version, confidence scores, routing decisions, and timestamps. It must also span the handoffs between stages. Recording extraction without its routing decision, or routing without the eventual agent action, produces only a partial log. Where documents directly drive financial or compliance decisions, the evidence must be field-level. Invoice extraction feeding payment posting, contract extraction feeding terms enforcement, and claim extraction feeding adjudication all require that granularity.
A decision to send a field to human review must retain the score that triggered it, while a human override must identify the reviewer. The record must not create a separate exposure. Requirements involving SOC 2, HIPAA, GDPR, zero data retention policies, and self-hosted deployment options belong in infrastructure design, rather than being treated as reporting concerns after the pipeline is built.
How the contracts interact: why a failure at any one stage compounds every stage after it
A parser drops a table row, extraction misses a field, validation passes the incomplete result, and the agent acts on it. Each stage can appear to have completed successfully. Yet every later result depends on the omission introduced at the start. Plausible confidence scores do not restore the missing source information, and a schema-valid handoff cannot make an incomplete document complete.
Chunking failures compound through a parallel chain. A segment ends mid-clause, embedding encodes the fragment, retrieval returns a near-match, and the agent synthesizes an answer from incomplete context. An audit record can expose that sequence, but cannot make the underlying action correct. Without the complete trace, the organization cannot reconstruct where the dependency chain broke.
This is why pipeline accuracy must be measured at document level. High field accuracy can coexist with one wrong field in every document. Each downstream system that uses those documents then gets an error, even though the results look good as a whole. Field-level provenance and document-level accuracy serve different purposes, with the former locating the defect and the latter revealing whether the document is fit for use.
What satisfying all six contracts looks like in a production pipeline
For teams implementing these contracts, the design principle is explicit enforcement at every boundary. Purpose-built ingestion infrastructure must handle changes in layout, multi-page context, and mixed formats without someone having to reconfigure it by hand, and must return structured representations with more than text alone. Stitched-together prompts are not a substitute for those guarantees. The relevant comparison is whether the infrastructure preserves the required relationships and detects violations.
Chunking must then match document structure, using hierarchical, semantic, or fixed-size strategies where each is appropriate. Section, page, and document identifiers must remain first-class chunk fields. Encoding must preserve the complete semantic unit. The index must keep the metadata needed to retrieve within the right section or document, and embedding and indexing must each be measured so failures can be traced to the stage where they arose.
Correctness requires the post-parse, post-extract, and pre-handoff checkpoints, backed by confidence thresholds calibrated against production document distributions. Failed checks must have a clear route to human review. The agent boundary then receives a versioned schema with typed fields, provenanced values, and no remaining cleaning work. An immutable execution trace must link those decisions to the final agent action with no gaps.
Enforcing the contracts over time takes instrumentation as well as checks at initial acceptance. Each stage needs its own latency, throughput, and error measurements, together with per-stage alert thresholds. Aggregate output accuracy cannot reveal a parse degradation until its effects have already propagated. The operational test is whether the pipeline can identify a broken guarantee at its source, route the failure, and preserve the evidence before an agent acts on it.