Migrating Off Brittle PDF Parsers to a Durable Agent Pipeline Foundation
A durable agent pipeline needs layout-aware parsing and calibrated confidence.
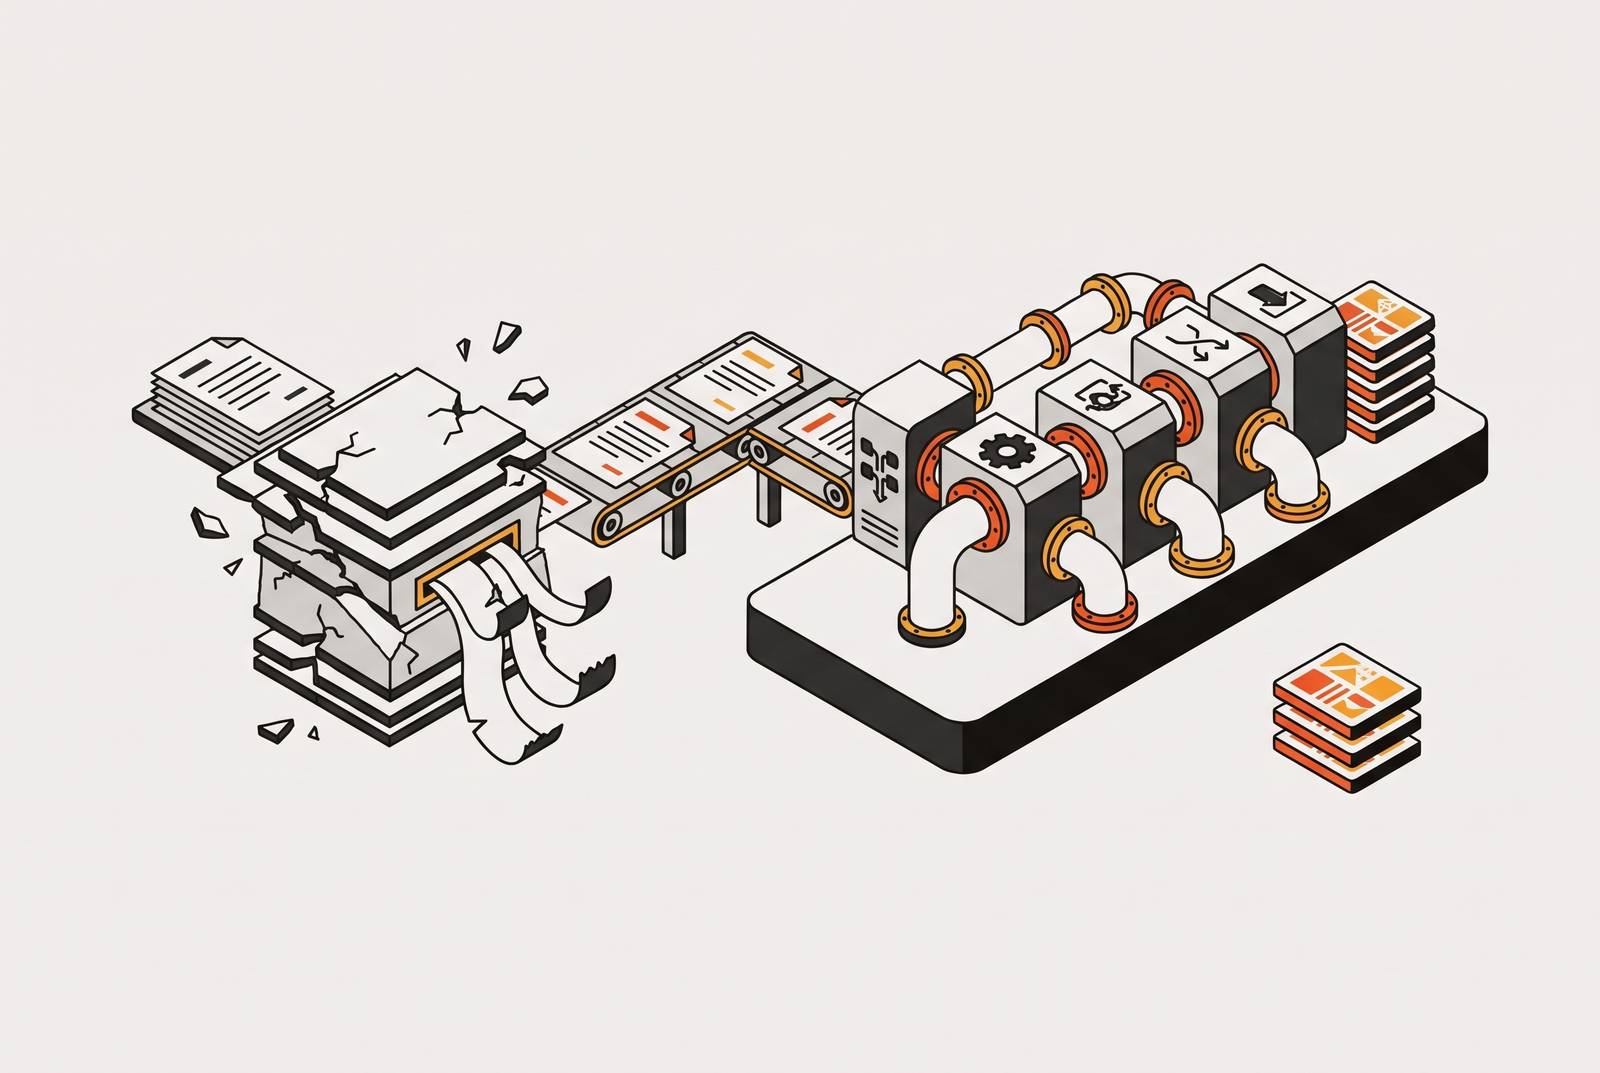
Migrating off brittle PDF parsers requires an architectural shift. Document processing infrastructure for AI agents must keep field meaning, table relationships, and reading order intact, then send results for review when it is unsure of them. A foundation that lasts brings together layout-aware extraction, adaptive routing, calibrated confidence, and production controls because getting the text right alone is not enough for agents to make reliable autonomous decisions.
Why PDF parsers that work in demos break in production agent pipelines
A vendor invoice arrives with columns shifted from their expected positions, and a coordinate-dependent extractor silently drops a field before it reaches the approval engine. The parser still appears to work. It produces text, but the relationship between a value and its field has already been lost. This is a structural failure, and downstream agent logic cannot reliably recover the missing relationship.
The PDF format is designed for visual appearance rather than machine consumption, so parsers must infer relationships that the format does not explicitly encode. Coordinate-dependent extraction classifies text regions by spatial position, making layout variation a source of misclassification before table reconstruction even begins. PyMuPDF, pdfplumber, Camelot, and Apache Tika each address well-defined extraction problems. Their limits emerge where format variability, processing volume, and field-level accuracy requirements intersect.
Table failures make those limits particularly visible. A full-width totals row can become a separate single-cell table, while an embedded sub-header can become a data row. Across page boundaries, header-to-column mapping can disappear and leave orphaned rows without field attribution. These errors survive successful character recognition. An agent approving a claim may therefore read the wrong value from a misaligned table, while an agent analyzing a financial report may lose the information it needs when a chart becomes raw text.
The gap between character-level accuracy and field-level correctness, and why it compounds
Character accuracy measures whether each character was read correctly. Field accuracy asks whether the right value reached the right semantic field, while structural accuracy concerns the relationships among tables, headers, columns, and multi-line entries. These layers can fail independently of one another. A shipper location mapped into the consignee field fails field accuracy even when every character is correct. A two-line location turned into one string can also pass character checks even though its structure has been lost.
The distinction extends from individual fields to entire documents. A single wrong field can invalidate a downstream record, so a strong average field score does not establish document-level correctness. High precision with low recall conceals omitted fields. High recall with low precision instead admits bad data, and neither condition is adequately described by character-accuracy scoring. When relationships break again and again across a document, downstream steps receive those errors along with any isolated transcription mistakes.
Four measures expose different parts of this gap. Field-level precision and recall describe correctness and completeness, character error rate captures transcription errors in sensitive numeric fields, and confidence calibration describes whether reported certainty predicts correctness. Document-level accuracy adds the consequence of those errors for the complete record. Results differ across groups of documents because of how predictable their layouts are, the quality of their scans, and their semantic density. Medical records and legal agreements are especially demanding because field meaning depends on surrounding context as well as position.
How to audit your current parser and locate where it actually breaks
Before writing migration code, look at the kinds of documents being processed in production. Separate clean born-digital invoices, scanned loan packages, multi-column layouts, and handwritten forms into distinct extraction problems. Each exposes a different kind of weakness. Use a held-out sample of real production documents to measure field-level precision and recall, with character error rate retained for serial numbers and numeric fields where transcription errors break validation.
Then test the relationships that agents depend on. Check whether header-to-column mapping survives page breaks, whether merged cells produce duplicated or missing values, and whether content arrives in human reading order. Compare stated confidence with actual field errors to establish whether confidence can support escalation. Record error classes separately, because dropped rows and scrambled reading order require different corrections even when their aggregate error rates look similar.
Inspect positional assumptions as part of that audit. Hardcoded bounding boxes, an optional Camelot feature rather than its default, are a strong warning sign when layouts vary and the pipeline has no detection mechanism. A good text-extraction score does not settle the question. The audit should map failure types to document types and rank those intersections by production volume. High-volume categories with high failure rates provide the strongest starting point for migration, while successful categories establish what need not change immediately.
What the benchmark evidence shows about parser accuracy across document types and failure dimensions
ParseBench, introduced in 2026, evaluates approximately 2,000 human-verified enterprise document pages from insurance, finance, and government. Its five dimensions are tables, charts, content faithfulness, semantic formatting, and visual grounding. No evaluated method is consistently strong across all five. This fragmented performance explains why a diverse production population cannot be evaluated through a single text-recognition score, and why universal routing to one parser leaves capability gaps.
The benchmark reports Infinity-Parser2-Pro at 74.3%, with Infinity-Parser2-Flash close behind. Differences between results on olmOCR-Bench and ParseBench show that academic and enterprise document distributions measure meaningfully different capabilities. Classic metrics such as character error rate, word accuracy, and BLEU on extracted strings do not expose incorrect column detection, row-wise reading errors, or confused column boundaries. ParseBench’s more than 169K test rules check a wider range of failures that matter to agents, including whether the structure is complete.
RealDoc-Bench separates layout accuracy from downstream Q&A accuracy across logistics, healthcare, financial services, and real estate documents. That distinction connects parsing performance to agent usefulness. For replacement evaluation, cover the five capability dimensions, test the actual domain distribution, and treat Q&A accuracy on real documents as the ground truth metric. Benchmarks remain incomplete substitutes for production samples. An architecture that lasts must therefore work with parsers whose strengths differ and catch failures that overall scores hide.
What infrastructure do AI agents need to process documents reliably?
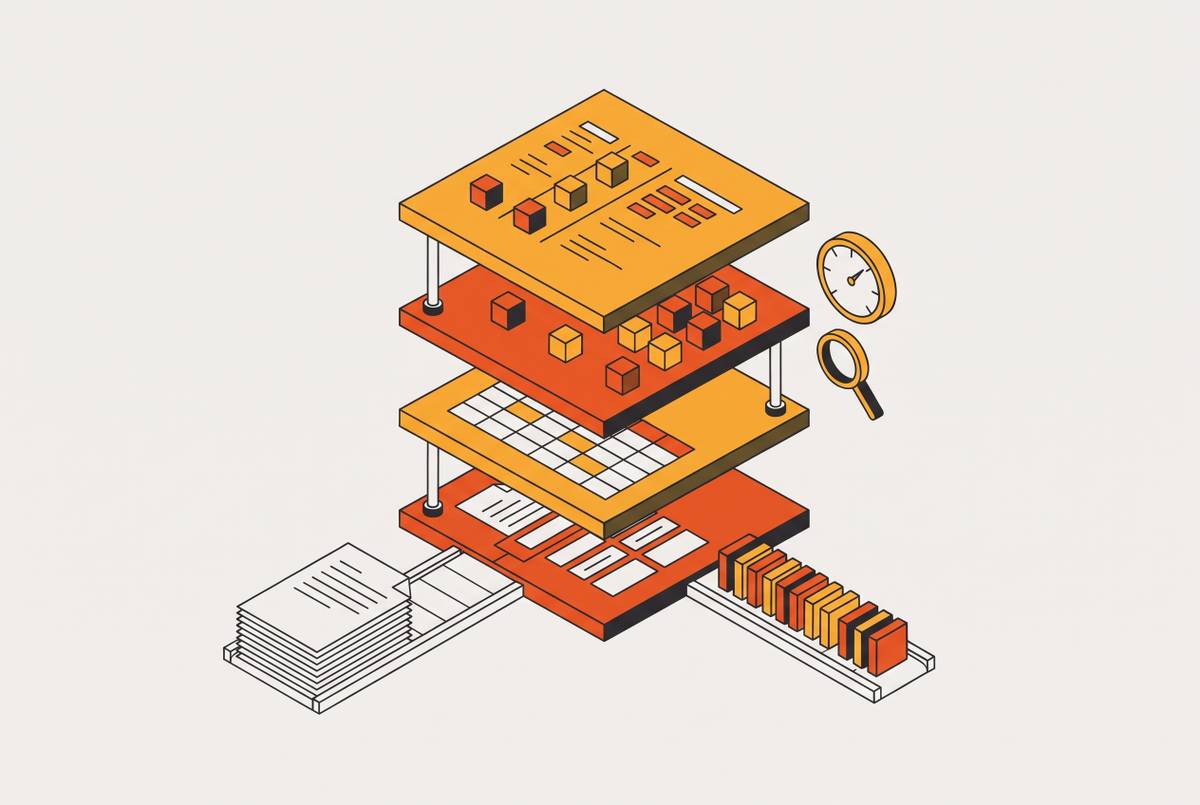
A fixed sequence of classification, OCR, template matching, and output remains brittle when documents deviate from its assumptions. Replacing the OCR component does not change that architecture. The parsing layer must handle layout detection, OCR, table structure reconstruction, and reading-order preservation as integrated responsibilities. Above it, routing must select an appropriate approach for each document, while error detection must expose missing structure before it passes downstream.
AdaParse, presented at MLSys 2025, supports this adaptive routing pattern. It first extracts text quickly to assess document characteristics, then uses machine learning to predict which parsing approach will produce the highest-quality output. It runs that parser while managing the computing resources used across multiple processing nodes. Selection becomes part of the system’s design. This differs from asking one extraction method to perform equally well on every document type.
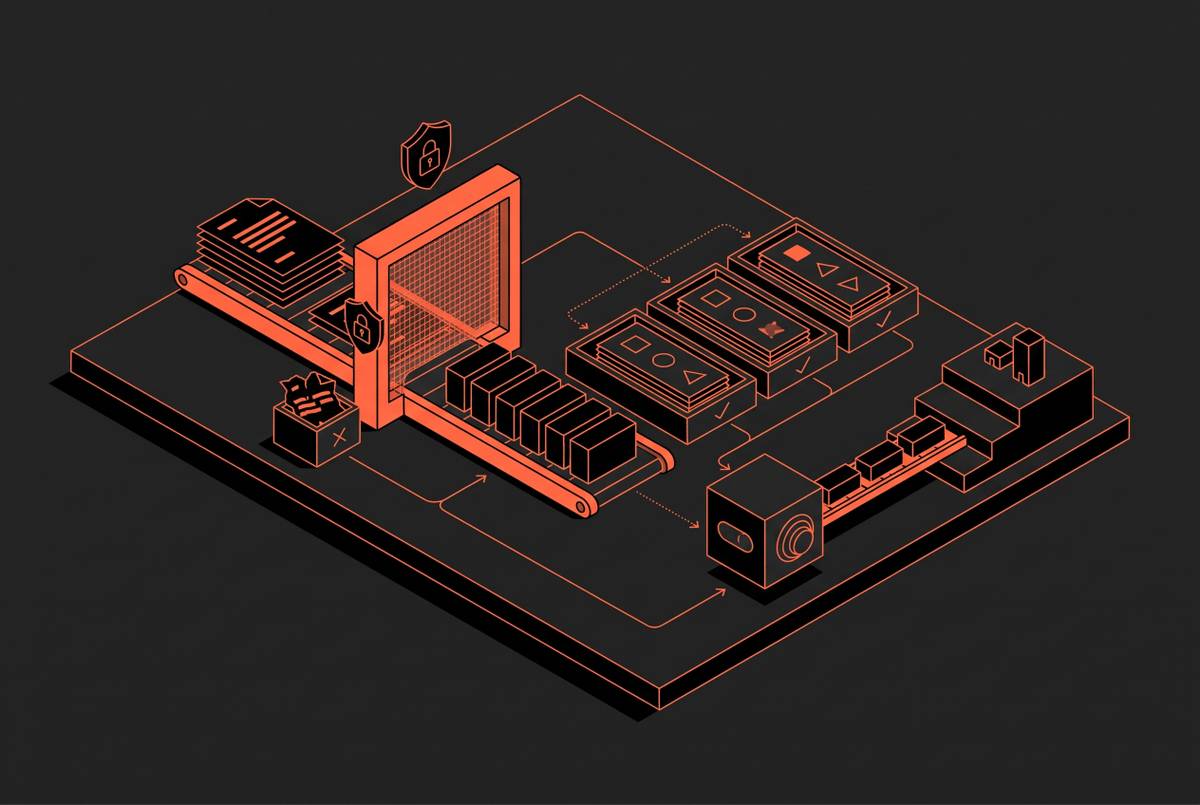
Confidence scoring sets the boundary between what runs automatically and what needs review. Documents above configured thresholds proceed automatically, while those below them route to human review. Both evaluation and runtime error detection must explicitly check for dropped rows in large-array extraction. Completeness cannot remain an incidental quality measure. The surrounding infrastructure must also support extraction, classification, and splitting without unnecessary vendor seams, and regulated deployments need security and deployment requirements addressed from the outset, including SOC 2, HIPAA, GDPR, and self-hosted options where required.
How to migrate without rebuilding from scratch through a staged approach
The first stage is to isolate ingestion from downstream agent logic so parsing can change independently. Where parsing and extraction logic are tightly coupled, decouple them before replacing components. Deployment constraints belong in this decision too. Teams subject to data residency, HIPAA, GDPR, or PCI requirements should evaluate self-hosted deployment at this stage rather than discover later that the selected path is unavailable to them.
The second stage is document-type routing based on the audit. Move the categories with both high failure rates and high production volume first, leaving clean born-digital documents on the existing path until the new path is validated. This limits the scope of the initial change. The third stage is to replace the extraction model with integrated layout inference, table reconstruction, and reading-order preservation. Extracting strings and then fixing their positions does not meet that requirement.
The fourth stage is to instrument confidence before go-live. Define thresholds for automatic processing and human review before the new path handles production volume. The escalation pattern described in the notes places the 85–90% of documents AI handles confidently above configured thresholds, but that range is not a guarantee for a particular document population. The policy’s credibility depends on calibration on held-out documents. Without it, the replacement can fail as silently as its predecessor.
The fifth stage is to test actual production documents using field-level recall and precision. RealDoc-Bench layout scores can inform the choice, but they cannot replace that test. Integration support also affects the migration schedule. A batteries-included layer with Python, TypeScript, Java, and Go SDKs, an open-source CLI, and agent skill templates can support production deployment in days rather than the months required for a bespoke rebuild. That possibility depends on the selected infrastructure and migration scope.
Where the structural and semantic failure modes are worst by industry, and what the pipeline must handle
In financial services and insurance, filings, policy documents, and regulatory submissions have both tables and dense prose. Success on structured invoices does not predict success on these hybrid formats. Charts introduce another structural dependency for financial analysis. Reducing them to text removes the structured data an agent needs, while a transposed digit in an account number or dollar amount can break downstream validation.
Healthcare adds handwriting and checkboxes to clinical documentation, prior authorization forms, and EOBs. Character recognition is only part of the task. Medical records have high semantic density, so a field’s meaning depends on surrounding context even when its text is legible. Misassigned values and scrambled reading order can therefore survive apparently successful OCR. HIPAA compliance and zero data retention requirements also constrain infrastructure choices, making self-hosted deployment or a HIPAA BAA prerequisites.
Real estate emphasizes the cost of missing contractual information. An omitted renewal option or termination clause is a more severe failure than a slightly imprecise extracted value, making field-level recall particularly important. Character accuracy cannot reveal that omission by itself. Evaluation must distinguish readable text from complete extraction of the provisions needed downstream. RealDoc-Bench includes real estate documents, so it offers a way to compare layout performance and downstream answers on documents from that field.
Logistics exposes positional assumptions through continuous format variation. Bills of lading, freight invoices, and customs documents arrive from many originators, so stable layouts cannot be assumed. Shipment line items can span several pages. Lost header mappings create orphaned rows, while changing carrier and shipper positions expose reading-order errors and field mismatches. RealDoc-Bench includes supply chain and logistics documents under the label supply_chain, so that subset can be used to test these specific kinds of failure.
What to look for when evaluating infrastructure options for the new pipeline
For accuracy, require enterprise-distribution benchmark results and held-out tests from the actual domain, covering all five ParseBench dimensions. Dropped rows need an explicit penalty. Average field accuracy can otherwise conceal incomplete large arrays, just as a strong character score conceals wrong field assignments. Confidence scores should also predict correctness on those same held-out documents.
API completeness determines how much coordination remains outside the infrastructure layer. A production-ready option should cover parse, extract, classify, split, and form fill, with workflow orchestration, schema versioning, batch processing, and a review UI included. Developer tooling affects the remaining integration work. SDKs in the team’s existing languages, an open-source CLI, and agent skill templates are concrete criteria to evaluate alongside extraction quality. Their value is reducing the work required to put validated capabilities into production.
Compliance requirements must be evaluated against the documents being processed. SOC 2, HIPAA, and GDPR requirements belong in that assessment, with zero data retention, BYOC, and self-hosted options available where PHI, PII, or PCI-scoped financial data demands them. Healthcare deployments also require HIPAA BAA availability. Operationally, configurable review thresholds and control over cost, latency, and accuracy allow different document types and risk tolerances to share an infrastructure layer without sharing one fixed policy.
To succeed in production, the pipeline must be much more accurate than the existing baseline on complex documents and show where it is unsure. Go-live in days is possible with integrated tooling, but neither speed nor accuracy follows from a parser’s headline score. Both must be shown to work in the intended workflow. The strongest foundation is the one whose structural correctness, review path, and deployment model fit the documents agents will actually use.
Sources
- ParseBench: A Document Parsing Benchmark for AI Agents
- Infinity-Parser2 Technical Report
- Doc Parsing: Open Source vs. Production APIs August 2026
- PDF Parsing API Guide (August 2026)
- 6 PDF Parsing APIs for AI Agents
- ADAPARSE: AN ADAPTIVE PARALLEL PDF PARSING AND RESOURCE SCALING ENGINE
- ParseBench: A Document Parsing Benchmark for AI Agents