Commercial Real Estate Lease Abstraction With Document AI
Automating lease data extraction requires tracing amendments and flagging uncertain fields.
Commercial real estate lease abstraction with Document AI must turn negotiated contracts into structured data that can be trusted as well as read PDFs faster. The output must support decisions by systems, agents, and analysts without concealing legal conditions or document conflicts. That requires a purpose-built extraction pipeline with traceable fields, amendment reconciliation, and confidence-gated review, rather than a general-purpose model applied directly to a lease.
Why commercial lease abstraction is harder than it looks
A commercial lease distributes its terms across negotiated clauses, exhibits, amendments, and side letters. Base rent may be easy to find, while the rules for its escalation depend on wording elsewhere. Renewal rights have deadlines for notice, co-tenancy requirements have remedies, and assignment restrictions have exceptions. Amendment lineage adds another dimension, because the abstract must establish which document supersedes which provision and on what date. Finding a value is therefore not the same as establishing the current obligation.
This makes lease abstraction different from rent-roll extraction, which deals with a table of numbers, or lender term-sheet abstraction, which captures defined debt terms. A lease abstract must preserve meaning in a structured record of typed values. The economically important fields include rent schedules, CAM charges and recovery methods, lease dates, option windows, transfer limits, and amendment lineage. Each value needs a reference to its exact clause and page, with a confidence score attached. That traceability lets a controller and a real estate director check a disputed renewal option without rereading the whole contract.
What the abstraction pipeline actually does, stage by stage
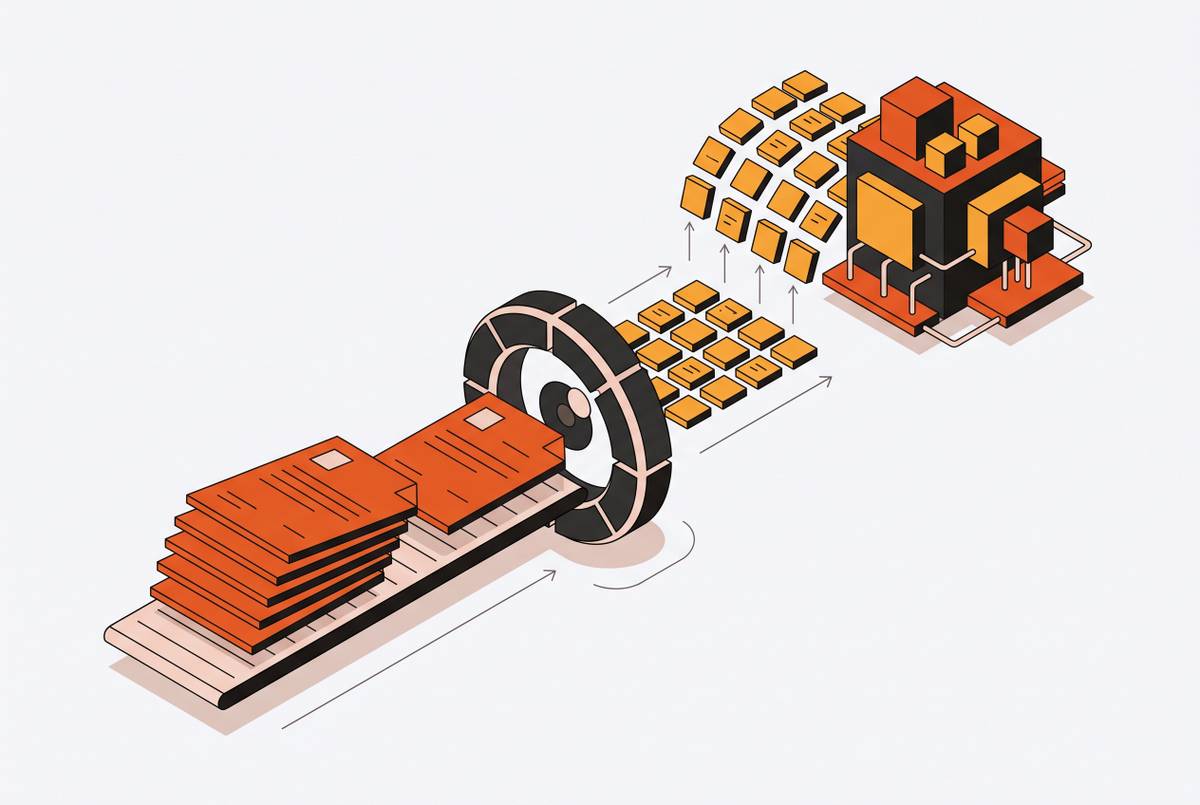
The pipeline begins with optical character recognition, or OCR, which converts scans and image-based PDFs into machine-readable text. Its accuracy depends partly on fonts and document quality, so errors can enter before legal interpretation begins. Classification and splitting then identify base leases, amendments, exhibits, and side letters and separate them for extraction. This prevents the system from treating a mixed document package as one undifferentiated contract. The quality of these early stages determines what evidence the extraction stage receives.
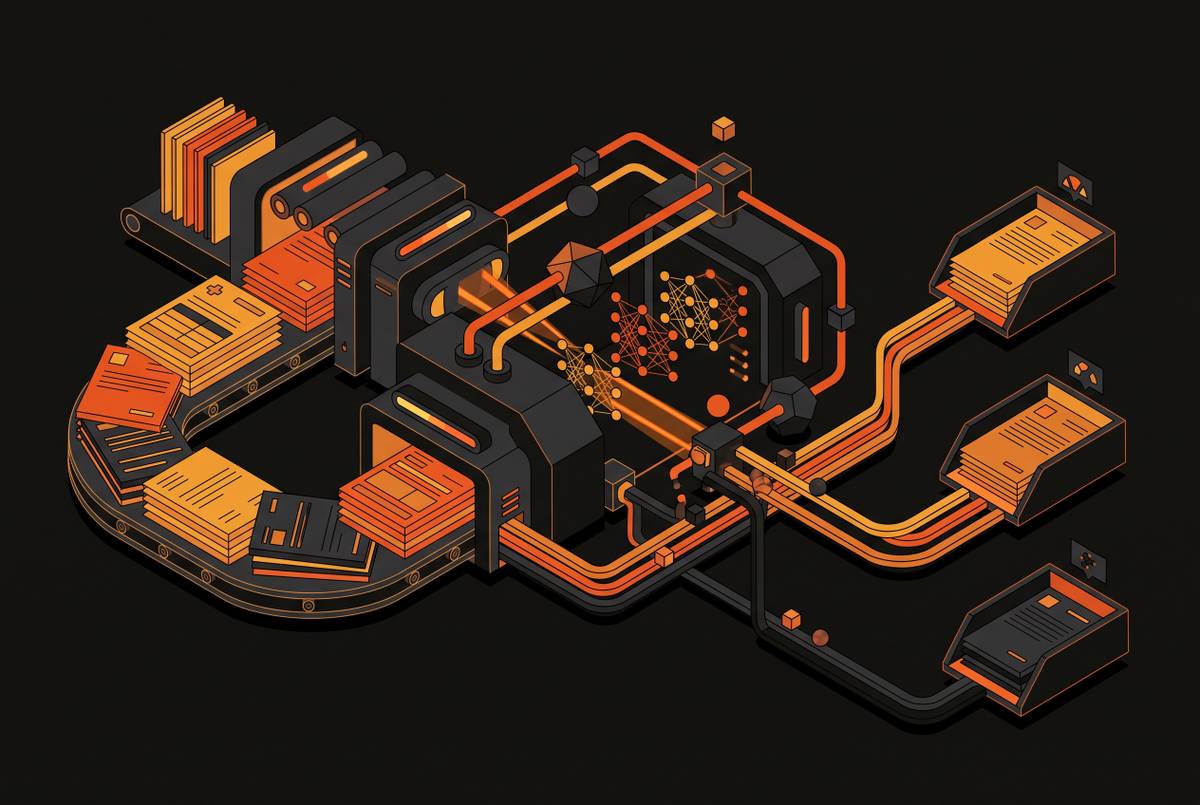
Natural language processing then identifies the passages carrying each provision by interpreting clause structure. A dedicated amendment reconciliation stage applies amendments, side letters, and notices to the provisions they change. Its output is one current lease position, rather than separate records that an analyst must reconcile manually. Assessment then assigns confidence at the field level and flags uncertain extractions for human review. A tool’s quality depends on how well this whole sequence works, because a strong extraction model cannot by itself correct every error introduced by document handling or missed amendments.
Where the pipeline plugs into the broader CRE workflow
In a CRE transaction, abstraction follows document collection and precedes detailed human analysis. It builds the rent roll, populates the critical-date calendar, and identifies clauses for attorney review. Because the automated pass takes minutes, it can run in parallel with title, survey, and environmental work. The record is then used for property management, financial modeling, compliance reporting, and legal review. These workstreams no longer need to reread the same lease independently, but they also inherit the same extraction errors.
Beyond transactions, portfolio operators use structured lease data to track renewal deadlines, rent escalations, and CAM reconciliations across hundreds or thousands of leases. When these terms remain buried in PDFs, critical dates can be missed and rent can go uncollected. Abstracted terms also provide a validation layer for recurring documents, including supplier invoices, utility bills, tax notices, and insurance certificates. Mature cross-document workflows can compare a rent roll, lease, and estoppel for the same tenant and surface discrepancies. With more work relying on abstraction, a wrong field can affect several decisions before anyone goes back to the source document.
Why headline accuracy numbers conceal field-level fragility
Even when per-field accuracy is high, an abstract with dozens of fields has many chances for an error. Each additional field adds another condition that must be satisfied for the entire record to be correct. A strong average score therefore does not establish that most complete abstracts are error-free. Nor does it show whether the errors are in administrative details or in provisions that set out what must be paid.
Document quality further limits the value of a headline score. Clean digitally generated documents and scanned or handwritten documents do not present the same extraction problem. A benchmark dominated by clean files may say little about performance on a portfolio containing degraded scans and heavily amended leases. The measure that matters is field-level accuracy on documents like those the team uses, with each field weighted by its effect on costs or income.
The five specific clause types where extraction fails most often
Rent escalation extraction can conflate compounding percentage increases with fixed-dollar increases or miss CPI floors. The value may look right even as it causes errors that compound over the lease term.
CAM reconciliation extraction can capture the recovery method but omit the base year, cap, or expense exclusions. Those omissions change the liability even when the broad description of the provision is correct.
Co-tenancy extraction can preserve the trigger, such as an anchor tenant departure, while dropping the remedy, such as rent abatement or a termination right. The abstract then describes when a right arises without retaining what the tenant can do.
Assignment and subletting extraction can miss permitted transfer carve-outs and landlord recapture rights. A negotiated exception then disappears behind what looks like a standard restriction.
Renewal option extraction can get the option term and rent right while getting the notice window wrong. The record may show an available option that expires before anyone acts on it.
These failures share structural causes: cross-references, conditions embedded in prose, and provisions whose remedy or exception appears pages away from the trigger. Having more fields does not make up for losing those links. Once an incorrect deadline enters a system of record, its apparent authority can be more dangerous than an obvious omission.
How confidence scoring and human-in-the-loop review address these failures in production
Field-level confidence scoring is an architectural requirement because uncertainty must reach the people and systems consuming the abstract. Every extracted field has a numerical confidence score that shows how likely the model thinks that extraction is to be right. Downstream thresholds should reflect the use case, with a lower threshold for bulk portfolio aggregation and a higher one for mortgage underwriting. Specialists then review only fields below the applicable threshold. This concentrates attention on uncertain dates, conditions, exceptions, and remedies while preserving the speed of the automated pass.
In multi-model consensus approaches, disagreement is another sign that a field needs review. The review loop also needs to capture human overrides as training signals, so a corrected rent step-up date can improve future extraction on similar clauses. Without that feedback, a system that is useful at first can stop improving because the corrections never feed into later work. Confidence-gated review is therefore not a concession to automation failure, but a way to combine fast extraction with targeted judgment and continued improvement.
What a production-grade lease abstraction pipeline looks like end to end
Built Technologies provides a concrete example of the surrounding infrastructure in real estate finance. Its pipeline moves documents through OCR, classification and splitting, extraction, assessment, and optional rule validation, with each stage running as a discrete function. Classified sections are extracted in parallel. When a 150-page draw package is split into constituent documents, concurrent extraction means processing time is bounded by the longest section. Classification and extraction workflows that previously took days now complete in minutes.
Built Technologies’ architecture supports more than 250 document types and is being scaled toward tens of millions of documents per month. Dynamic schema generation lets users upload examples of a new document type and receive a proposed extraction schema. Subject matter experts refine and test that schema before production, without engineering involvement in every new document type.
An agentic layer adds a further separation between evidence gathering and judgment. Fact extraction gathers evidence from relevant document sections, after which orchestration reasons over that evidence and returns a determination with citations. Separating those tasks is especially important for long documents whose relevant provisions are dispersed.
Why general-purpose models are not sufficient for this pipeline
A general-purpose foundation model can read lease language, but it needs more than that ability to serve as a full production pipeline. Classification before extraction, amendment reconciliation, and field-level confidence scoring are not native workflow stages of a model. They must be built around it. The same is true of handling reading order, complex layouts, and relationships between fields. The limitation is an infrastructure gap.
A better prompt alone does not establish which amendment controls a clause or route an uncertain notice deadline to a specialist. Those tasks need their own processing stages and rules for review. Improvements to splitting, parsing, and extraction depend heavily on this surrounding system, rather than solely on the frontier model underneath it. Scanned and handwritten documents make that distinction more important because the evidence itself may be harder to recover. A fast first pass is useful, but plausible output without traceability and uncertainty handling is not enough for downstream agents or financial systems to trust.
What to evaluate when choosing a lease abstraction platform or infrastructure layer
Choosing a platform should start with how it handles the files the team actually receives. The tests need to show how accuracy changes across native PDFs, scans, handwritten material, and multi-page packages. Amendment handling must then show that it can bring separate extractions from each document into a single current lease position. Field-level confidence should be numerical, with review queues that can be filtered by thresholds for different field types. These features let the platform show where a value is uncertain before it is used to make a financial decision.
Schema configurability matters because teams need custom fields, jurisdiction-specific provisions, and property-type-specific clauses without a new implementation cycle. Integration matters for a related reason, since structured output is less useful in day-to-day work if staff must re-enter it by hand into Yardi, MRI, or internal dashboards. The platform should support that flow through an API. Time to production is also a substantive criterion. An implementation requiring months of onboarding creates a structural risk when due diligence timelines are measured in weeks.
How to run a reliable accuracy evaluation before committing to a platform
Start with a test set drawn from the actual portfolio, including clean digital leases, scanned leases, heavily negotiated leases with multiple amendments, and non-standard clause structures. Do not limit the sample to the cleanest documents in the data room. Measure accuracy separately for rent escalations, CAM reconciliation, co-tenancy, assignment and subletting, and renewal options. Weight errors by their effect on costs or income, since a wrong renewal notice window may have a greater financial effect than a wrong administrative fee cap. This establishes a baseline that reflects the work the system will perform.
Next, test amendment reconciliation explicitly by uploading a base lease with two amendments and checking that the output reflects the final amended state. Then check confidence calibration by comparing the scores with the errors in the extractions. Wrong fields should receive lower confidence, while uniformly high scores regardless of correctness provide little value for triage. The test must distinguish a useful review signal from a number merely attached to an answer.
Finally, before putting the platform into wider use, check whether it records human corrections as training signals. A baseline can support improvement only if overrides enter the learning loop. The aggregate accuracy a vendor reports cannot take the place of this process because it shows how the system performed on a different set of documents under different conditions. A representative, field-level evaluation is itself part of the infrastructure. Teams that skip it are shipping without a test suite.