SEC Filing Document Parsing for Financial Data Extraction
Reliable SEC data extraction requires parsing narrative, tables, and XBRL together.
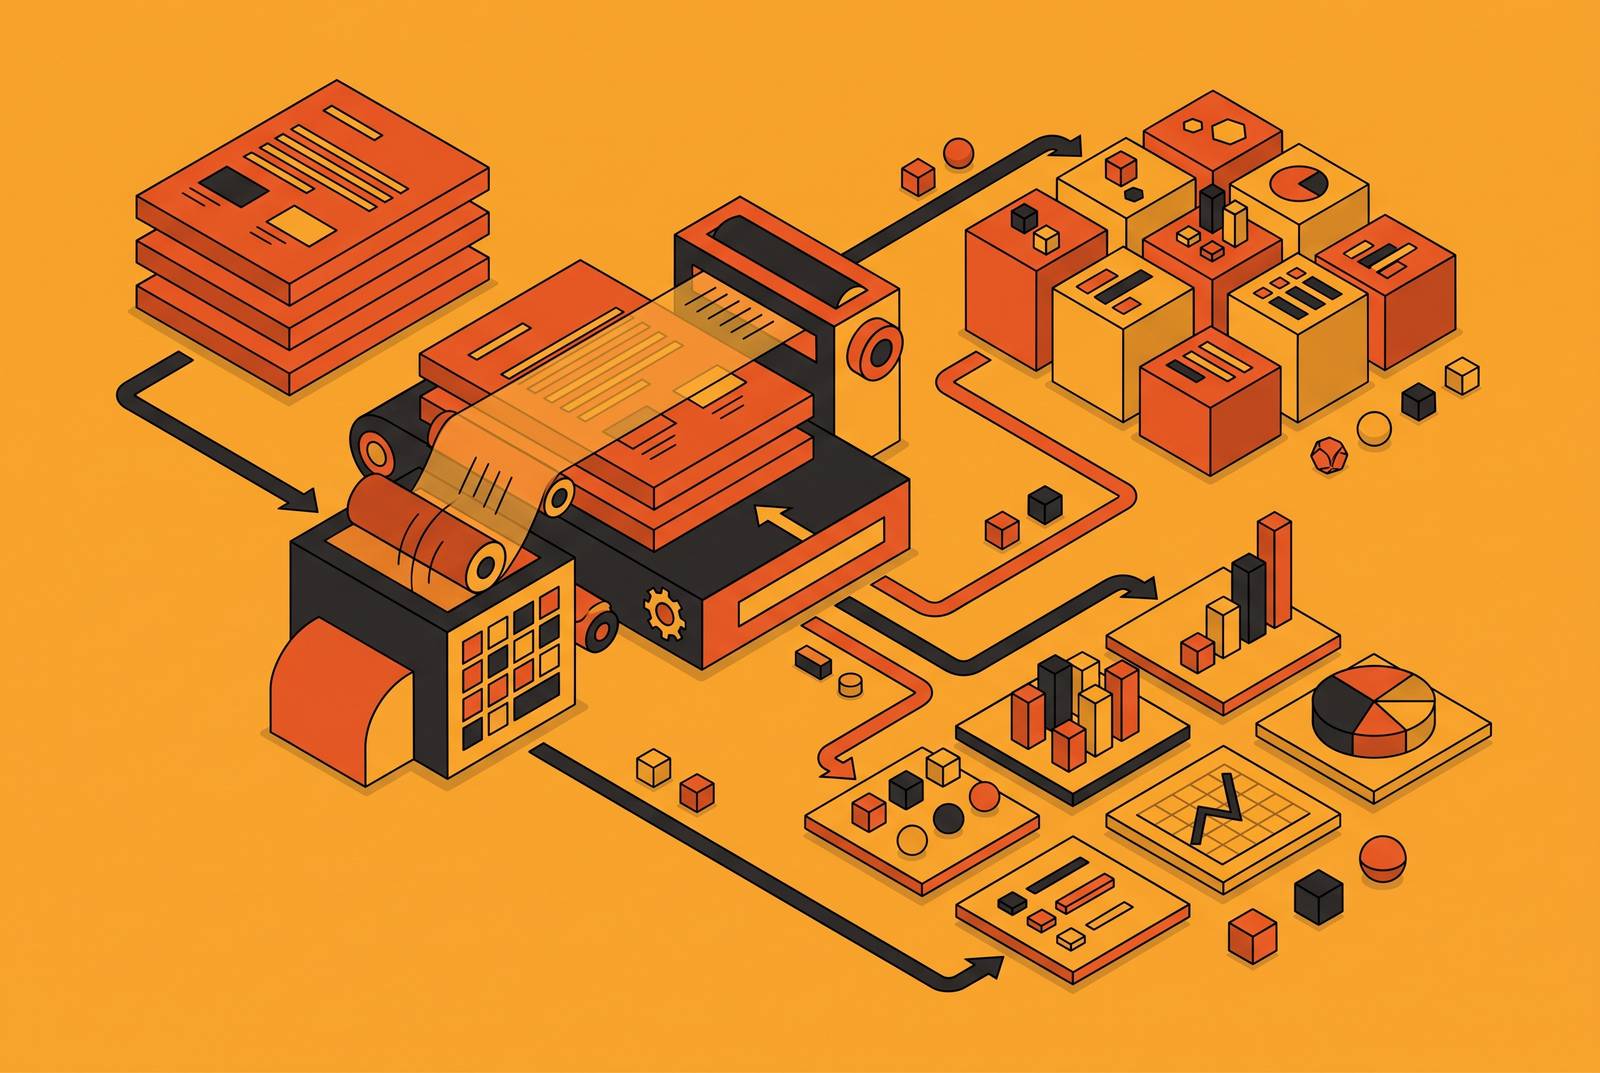
SEC filing document parsing for financial data extraction requires more than converting a document into text. Reliable extraction depends on reconciling narrative disclosures, financial tables, and XBRL facts through separate parsing, extraction, and reasoning layers. A pipeline that reads only the easiest representation can produce plausible structured output while silently omitting or misinterpreting the evidence that financial decisions require.
Why SEC filings are structurally hostile to automated extraction
A negative equity figure may appear as a parenthetical in prose, a bracketed table cell, and an XBRL fact with an encoded sign convention. The financial value is the same, but the evidence needed to interpret it differs. A text reader encounters punctuation, a table parser encounters spatial relationships, and an XBRL parser encounters tagged meaning. These are not interchangeable copies of one disclosure. Narrative prose, tabular financials, and machine-readable tags are parallel structures whose information overlaps without being fully redundant.
Inline XBRL is mandatory for most filers, while PDF is only an unofficial supplement, and requirements vary by filer category and form type. A parser therefore cannot count on the same kind of input even in filings from the same company. Nor does one extraction schema transfer cleanly between 10-K, 10-Q, 8-K, proxy statements, and registration statements. Each has different section structures, boilerplate distributions, and locations for material disclosures.
Longer filings make these differences harder to handle and take more time to process. Real 10-K filings routinely exceed the context windows of widely used models, forcing section-level splitting or escalation to higher-context models. Neither choice is neutral for accuracy. Splitting changes which evidence the model sees together, while a larger context window still leaves it with different structures to interpret.
What the EDGAR data layer actually provides and where it runs out
The SEC’s official EDGAR APIs give access to submissions history and extracted XBRL financial facts without an API key. That gives engineers direct access to structured numeric data for a large portion of reported financials. The boundary is equally important to understand. EDGAR does not provide narrative section text, reading-order reconstruction across complex layouts, cross-reference resolution between footnotes and primary statements, or confidence signals for the extracted XBRL values. Access to a reported fact is therefore not equivalent to having the evidence needed to interpret it.
sec-api.io offers filing queries, full-text search, and section extraction using a filing URL and item code. Valyu returns relevant passages with original source URLs in response to natural-language queries. Financial Modeling Prep offers filing discovery along with broader financial data endpoints, but it does not return evidence passages ranked in order. These are different retrieval functions.
The distinction becomes consequential when an agent decides what to fetch. Document discovery identifies the filing, while evidence retrieval locates the material needed to answer a question. An agent may retrieve an entire section when it needs a passage, or retrieve a passage when compliance requires the complete section. The infrastructure supplies access, but the extraction workflow still has to define the appropriate evidence boundary.
XBRL, HTML, and PDF are not equivalent input formats — the parsing ceiling differs for each
The input format limits how accurate the results can be before a model is chosen or given a prompt. Controlled pilot evidence places XBRL ahead of PDF and PDF ahead of HTML for the financial extraction tasks evaluated, with XBRL requiring more tokens. That order depends on the task. PDF remains particularly error-prone for complex tables and difficult reading-order reconstruction, while HTML preserves document structure but loses inline metadata when consumed as plain HTML without inline XBRL parsing.
XBRL’s advantage for reported numeric facts comes from its taxonomy and encoded relationships. Those structures help with ratio calculation across periods, trend detection, segment revenue analysis, and subsidiary-level disclosures in ways that are hard to match with HTML and PDF. Sign handling illustrates both the benefit and the limit. XBRL structurally encodes sign conventions, but sign errors remain among the most common tagging mistakes. Machine-readable meaning is not a guarantee of correctness.
FinAuditing reports very low accuracy for its strongest evaluated model on numerical consistency verification across XBRL filing hierarchies. That benchmark identifies an unresolved verification problem. For institutional-grade extraction, the implication is to retain XBRL support and budget for its token-cost premium rather than defaulting to the cheapest representation. Narrative and table parsing alone cannot supply all the precision these workflows require.
Why single-pass LLM extraction fails on the data that matters most
Single-pass extraction collapses retrieval, extraction, calculation, and verification into one generation step. Feeding a filing or section to a model and requesting structured output can work on a bounded question, but financial analysis often requires cross-page evidence and temporal comparison. Those demands expose the architectural weakness. The model must find the right evidence, interpret it, and reason over it without distinct stages at which those operations can be assessed.
FinMMDocR, presented at AAAI 2026, makes the workload concrete. Its expert-annotated problems take an average of 11 reasoning steps, with 5.3 extraction steps and 5.7 calculation steps, and most need cross-page evidence. No evaluated model exceeds roughly half accuracy. Open-source models tend to do worse, but some proprietary models score below the best open-source model.
Fin-RATE finds that accuracy drops sharply as tasks move from single-document reasoning to cross-entity and temporal analysis because of comparison hallucinations and entity mismatches. FinRetrieval finds a much larger retrieval-accuracy gap between tool configurations than between model architectures. Retrieval should be separated from reasoning, with verification treated as a distinct concern. For cross-period, cross-entity, and footnote-dependent tasks, that separation is a prerequisite.
The demonstration-to-production gap and why it swallows most pipelines
A correct demonstration proves that a pipeline can produce an answer under the tested conditions. It does not establish dependable operation across repeated runs and changing documents. A July 2026 paper evaluating document-heavy workflows across model families and tool configurations found that a majority cleared a demonstration bar of one correct run, but only roughly half cleared its production bar. That bar combined sustained accuracy, reproducibility, verifiable attribution, and an informative confidence signal.
Sustained accuracy means that success persists across the document variety the workflow must handle. Reproducibility asks whether repeated execution remains dependable. These test different properties of the pipeline. A system may extract a field correctly once but fail on later runs, while an answer it gives every time may still be wrong. Production evaluation has to distinguish those cases.
Verifiable attribution requires an output to be connected to evidence that supports it. A filing reference alone is insufficient when the question is whether a particular passage or financial fact justifies the answer. Confidence adds a separate routing requirement. It must help separate outputs that can go through automation from those that need review, beyond giving each result a number that looks reassuring. Attribution establishes support, while confidence informs how the result should be handled.
Academic financial extraction benchmarks report results from below twenty percent to above ninety percent, depending on the task, how complex the schema is, and the dataset. Those scores do not describe one transferable level of capability. Dataset bias, document diversity, and enterprise integration contribute to the shortfall between curated evaluation and production performance. Accuracy is therefore a property of the complete workflow under its operating conditions.
Why self-reported confidence scores cannot be trusted for financial extraction
Asking a model how confident it is does not supply the production signal described above. Vision-language models often give saturated, overconfident scores that do little to tell correct extractions from incorrect ones. A confident answer can still be wrong. In a financial pipeline, that creates a direct route for silent failure, because an incorrect figure can pass an automated quality gate and feed ratio calculations, trend analysis, or compliance filings before the error is detected.
Perception, Layout, and Validation, accepted at the RobustifAI Workshop at IJCAI-ECAI 2026, demonstrates a stronger approach using multiple signals. Its decomposed conformal layer combines perception signals, layout signals, and validation channels to improve separation between correct and incorrect extractions. The architectural distinction is straightforward for engineers. Confidence comes from evidence about the extraction process and its validation.
That distinction makes selective prediction operationally useful. Low-confidence extractions can go to people for review while high-confidence extractions go through automatically. Confidence should be built into the extraction layer as a first-class output and calibrated against actual error rates on the target document corpus. Having the model score its own output after generation does not provide that calibration.
How a production-grade pipeline separates parsing, extraction, and reasoning into distinct layers
A production-grade pipeline should put parsing, extraction, and reasoning in separate layers, each with its own accuracy requirements and checks for failure. Parsing converts raw filings into structured representations with correct reading order. Extraction produces typed financial facts with attribution and calibrated confidence. Reasoning uses those facts to do calculations, make comparisons, and put together a narrative. Retrieval supplies the relevant evidence without making its discovery inseparable from answer generation.
At the parsing layer, format routing should use XBRL endpoints for reported numeric facts where available and HTML section extraction for MD&A, Risk Factors, and footnotes. PDF parsing is the fallback where neither is accessible. The sign conventions still need to be checked for every numeric source. At the extraction layer, the workflow retrieves filings from EDGAR by CIK and period, identifies the correct section, and extracts typed facts with source passage links. Both the fact and its provenance pass to reasoning, rather than extraction and reasoning occurring in the same call.
Before comparison, the reasoning layer should perform explicit entity resolution and period normalization. This addresses the mismatches that make cross-entity and temporal analysis less reliable than single-document tasks. Structured facts still need their narrative context. Combining XBRL with MD&A, Risk Factors, and financial statement footnotes reflects where material disclosures actually reside, rather than privileging whichever source is easiest to process.
For audit-grade applications, this architecture needs to include human review. Selective prediction routes uncertain extractions to reviewers while preserving automation for outputs that meet the calibrated confidence threshold. It is a throughput and reliability mechanism. Review, attribution, and validation must remain connected to the extracted fact rather than detached from it in a downstream reporting step.
Compliance requirements that pipeline architecture must satisfy, not retrofit
SEC Rule 17a-4 constrains recordkeeping design from ingestion onward. Its 2022 audit-trail alternative is one of two permitted approaches, with WORM storage as the other. The alternative requires a complete, time-stamped audit trail of modifications and deletions and, where applicable, the identity of the individual creating, modifying, or deleting a record. A separate provision requires automatic verification of the completeness and accuracy of electronic storage and retention processes. These are related but distinct obligations.
The rule does not explicitly identify automated systems as actors or mandate a traceable system identifier. Ordinary AI output logs are not sufficient by assumption. Broker-dealers must satisfy the applicable recordkeeping approach, including non-rewriteable, non-erasable storage where that approach is used. The SEC’s FY2026 examination priorities also focus on how AI use is supervised and whether claims about it are accurate, so AI governance is part of being ready to deploy.
The OCC, Federal Reserve, and FDIC issued Model Risk Management: Revised Guidance in April 2026. OCC Bulletin 2026-13 superseded OCC Bulletin 2011-12, while the Federal Reserve’s SR 26-2 separately superseded SR 11-7. The guidance excludes generative and agentic AI from formal scope as “novel and rapidly evolving” and anticipates a request for information. The framework is therefore still forming. Architecture must accommodate future requirements without wholesale reconstruction.
The practical design response is to place controls at the layer where they operate. Ingress handles redaction and tokenization of non-public information before inference, while retrieval applies permission-aware, document-level access controls. Agents operate under tiered autonomy and human approval gates, and logging produces immutable decision records. Enterprise requirements for security, privacy, retention, and deployment options also constrain whether the pipeline can be used. For engineers choosing infrastructure, compliance and accuracy are inseparable because the same fragmented filing structure that complicates extraction can conceal errors whose evidence, handling, and downstream use must remain accountable.